How LLMs Work: Next-Token Prediction Explained Simply
-
Last Updated: October 5, 2026
-
By: javahandson
-
Series

Learn how LLMs work through next-token prediction, explained simply for Java developers. Tokens, embeddings, attention and what it means for Spring AI.
Every Spring AI app you build talks to a large language model. You send a prompt. You get back an answer. But what really happens inside that black box? In this guide, we will open the box and look at next-token prediction, the one simple idea that powers every LLM.
In the earlier articles of this series, we connected Spring Boot to OpenAI and Ollama. We called ChatClient and we got replies. Now let us slow down and study the engine itself. Once you know how the model thinks, prompts and tokens will finally make sense.
This article builds on the foundations from our Spring AI course. By the end, you will understand:
There is no heavy math here. We will use plain language and small examples instead. So let us begin.
Before next-token prediction, let us place LLMs on the map. People mix up terms like AI, ML, and deep learning all the time. So here is a quick, clean picture to clear the fog.
Think of it as a family tree. Each box sits neatly inside the bigger one.
Analogies make this easy. So imagine you are building a robot chef.
In short, an LLM is a deep learning model trained only on text. Now let us open up its one real job.
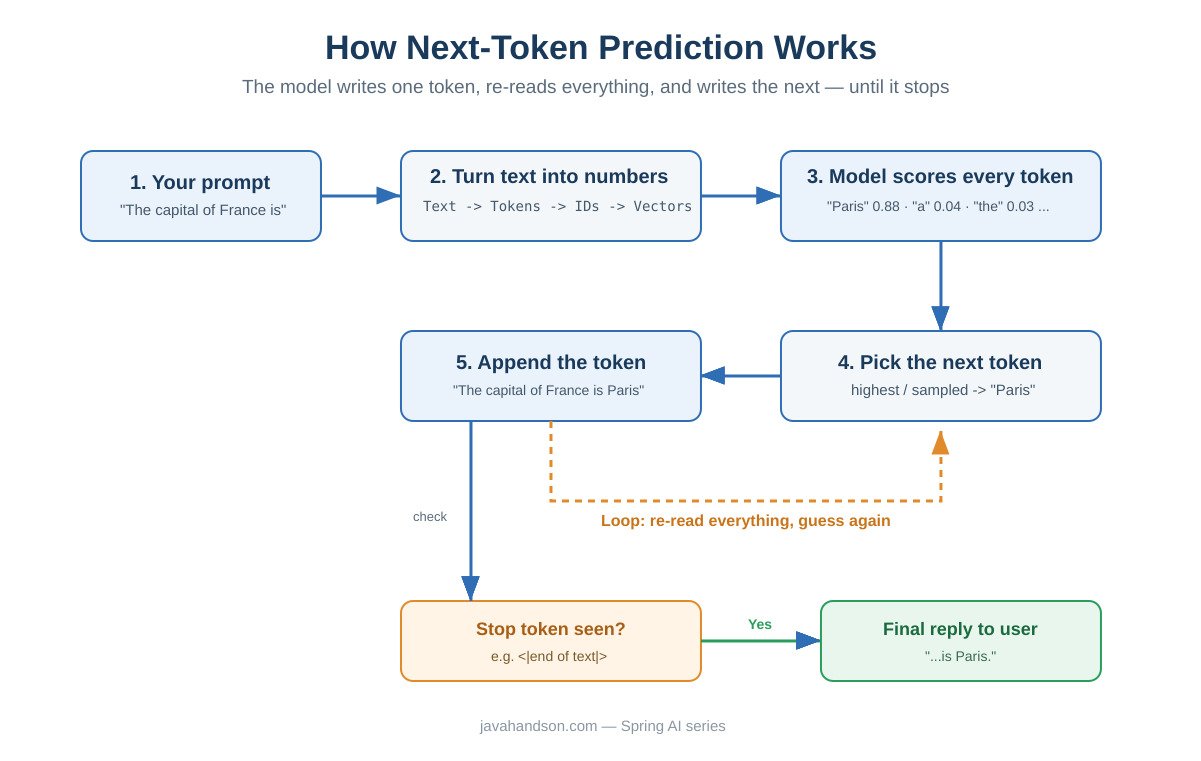
Here is the big secret. An LLM has just one main job. It guesses the next token based on the text so far. That is it. Everything else is built on top of this single trick.
Think of it as a very smart autocomplete. Type “Once upon a” and the model guesses “time”. Type “The capital of France is” and it guesses “Paris”. The model simply predicts what comes next.
This is a fair doubt. If the model only guesses one token, how do you get a full answer? The trick is clever yet simple. The model eats its own output.
Here is the loop in plain words:
So a long reply is really this tiny step run hundreds of times. The model keeps nothing in its head between steps. Each pass starts fresh and re-reads everything.
The raw LLM is only the engine. A tool you chat with, like ChatGPT, wraps around that engine.
This wrapper keeps feeding text back to the engine. It collects each guessed token and stitches the full reply for you. On top of that, it manages chat history and the chat interface.
The model can also predict special tokens. One of them means “stop here”. A common example looks like a marker such as “end of text”.
When the wrapper sees that stop token, it ends the loop. Without such a signal, the model would just keep writing forever. The wrapper also marks where your prompt ends, so the model knows a reply is expected.
| 💡 Interview Insight A common question is: “Is an LLM just a fancy autocomplete?” The honest answer is yes, at its core. It predicts the next token from context, one step at a time. What feels like reasoning emerges from doing this at a huge scale, with billions of parameters and a lot of training data. |
Earlier I said the model guesses the next word. That is not fully correct. It guesses the next token. Let me fix that idea right now.
A computer cannot read text directly. It only understands numbers. So every piece of text is first broken into tokens, then turned into numbers. This breaking step is called tokenization.
A token is a small piece of text. It is not always a full word, though. It can be many things.
For GPT-4, one token is roughly three-quarters of a word. So about 100 tokens equal 75 words. Keep this ratio in mind when you think about cost.
Whole words cause real trouble. Some words are rare, like “unconstitutional”. Some are misspelled, like “gud”. Others are brand new, like a fresh product name. And a few languages do not even use spaces.
Characters are too small, on the other hand. To read “unbelievable” letter by letter, the model needs twelve separate steps. That makes training slow and understanding harder.
So tokens sit in the sweet spot between words and letters. Take the made-up word “playfulish”. The model may split it into “play”, “ful”, and “ish”. Even though the word is new, the model still handles it with ease. This is how models cope with typos and slang.
Every model has a fixed vocabulary. This is a giant table that maps each token to a unique number, called a token ID.
For example, a model might store these:
Vocabulary sizes differ from model to model:
What if a word is missing from the table? The model splits it into smaller known pieces. So “tabletop” becomes “table” and “top”. If “top” is also missing, it splits further. This clever fallback is called subword tokenization.
The full journey now looks like this:
Text -> Tokens -> Token IDs -> Vectors
We have covered the first three stages. Next comes the most interesting one, the vectors.
Here is a point many beginners miss early on. Model providers charge you by tokens, not by words. So a chatty prompt with long history costs more than a short one.
Your input tokens and output tokens both count. A big system prompt adds up on every single call. Therefore, trimming prompts is a real way to cut cost in a Spring AI app.
A token ID like 1342 is just a label. It carries no meaning on its own. The number for “King” is not “bigger” than the number for “apple”. So how does the model grasp meaning? The answer is embeddings.
An embedding is a list of numbers, also called a vector. Each number shows how strongly a token relates to some hidden concept.
Instead of seeing “King” as four letters, the model sees something like this:
"King" -> [ 9.5, -8.0, 7.5, 6.0, ... , 2.0 ]
Imagine the first few numbers stand for topics like royalty, gender, and leadership.
Now look at the vector for “Queen”:
"Queen" -> [ 9.5, 8.0, 7.0, 5.5, ... , 2.0 ]
It stays close to “King” in royalty and leadership. Yet it flips on the gender number. Pretty neat, right?
My example used five numbers only. Real models use thousands of them.
These long vectors live in a high-dimensional space. We cannot picture such a space. Still, the idea holds firm: similar words end up close together.
Here is the magic that surprises almost everyone. You can do math with meaning itself.
embedding("king") - embedding("man") + embedding("woman") ~= embedding("queen")Read it in plain English. Take “king”, remove the “maleness”, then add “femaleness”. You land right near “queen”. The model never learned a label called gender. It picked up these patterns on its own during training.
The same trick works for geography too:
embedding("capital") + embedding("France") ~= embedding("Paris")So word relationships become simple arithmetic. This is exactly why LLMs handle analogies so smoothly.
At the start of training, each vector is random. It means nothing yet. Then the model reads sentences like these:
Every time it guesses wrong, the model nudges the numbers a little. After billions of examples, the vector for “king” settles near “queen”, “prince”, and “royal”. Nobody labels these links by hand.
Embeddings let us compare meaning with simple math. To check if two words are related, the model uses a trick called the dot product.
You multiply matching numbers and add the results. A quick example makes it clear:
"King"  = [9, -5, 6]
"Queen" = [8, -4, 6]

dot = (9x8) + (-5x-4) + (6x6)
    =  72   +   20    +  36   = 128   -> strong similarity
A high score means close meaning. Scores near zero mean the words are unrelated. And a negative score flips to opposite meanings. This one simple idea powers search, RAG, and recommendations in Spring AI.
| 💡 Interview Insight Interviewers often ask how a model knows that two words are similar. Do not say it compares spellings. It compares their embedding vectors, usually with a dot product or cosine similarity. A high score means close meaning, and a low or negative score means unrelated or opposite words. |
We now have vectors for meaning. But there is still a gap. One word can mean very different things. So a single fixed vector is not enough.
The basic vector for a token never changes. These fixed vectors are called static embeddings. They work, but only up to a point.
Take the word “bank”. It has one static vector. Now look at these two sentences:
Same word, yet very different meaning. A fixed vector simply cannot tell them apart. So the model needs something smarter on top.
First, a quick side note about word order. A transformer looks at all tokens at once. So it does not naturally know which word came first.
But order carries meaning. “The cat sat on the mat” is not “The mat sat on the cat”. To fix this, the model adds a positional embedding to each token. Now every token knows both its meaning and its place in the line.
Here comes the real hero of modern LLMs. Attention lets the model focus on the right words. Think of it as a smart highlighter.
For each word, the model quietly asks: “Which other words matter most for understanding this one?” Then it scores those words.
Back to “bank”. In the first sentence, the model sees “deposit” and “money”. These push the meaning toward a finance bank. In the second sentence, it sees “river” and “sat by”. These push it toward a river edge.
So attention gives scores to nearby words:
This is why context changes meaning on the fly. Static embeddings alone cannot do this. Attention can, and that is its superpower.
Let us zoom out and see the full flow once. It helps to view all the pieces as one chain.
Then the loop runs again for the next token. So a reply is just this pipeline repeated, step after step, until the stop token arrives.
You might wonder who teaches the model all this. The surprising answer is nobody, at least not directly. The model mostly teaches itself.
LLMs learn through self-supervised learning. Nobody labels the training data by hand. The text itself provides both the question and the answer.
It is a lot like a baby learning to speak. A baby hears thousands of sentences. Slowly it spots patterns, like “after good usually comes morning”.
The model plays the same guessing game:
Repeat this across billions of sentences, and strong patterns slowly take shape.
The scale is hard to imagine. For GPT-4, public estimates suggest some wild numbers.
A human reading day and night would need about 114 years to read that much. The model reads it, learns the patterns, and keeps them.
Training needs huge amounts of simple math. Most of it is vector and matrix operations repeated endlessly.
So GPUs are far faster for this kind of parallel work. That is why every large model is trained on them.
Theory is nice. But you are a Java developer at heart. So let us connect all this back to real Spring AI code.
Everything you tune in ChatOptions now has a clear meaning. These settings control the next-token step directly.
Here is a quick reminder of how you set these in code:
var options = OpenAiChatOptions.builder()
        .model("gpt-4o-mini")
        .temperature(0.7)
        .maxTokens(500)
        .build();

String reply = chatClient.prompt()
        .options(options)
        .user(message)
        .call()
        .content();
Two more ideas click into place as well.
This series uses Spring AI 2.0.1, the current stable release on the 2.0 line. It arrived in August 2026 as the first maintenance update on top of the 2.0.0 GA from June 2026. The core ideas here do not change across versions, though. Next-token prediction stays the same whether you call OpenAI, Ollama, or AWS Bedrock.
| 💡 Interview Insight A favorite question is: “Why does the same prompt give different answers each time?” The reason is sampling. The model picks from a spread of likely tokens, not one fixed answer. Lower the temperature, and the replies become far more stable and repeatable. |
A: Next-token prediction is the single job behind every LLM. Given all the text so far, the model scores every token it knows, picks one, appends it, then re-reads everything and predicts again. Long replies are just this tiny step repeated until a stop token appears.
A: At its core, yes. It predicts the next token from context, one step at a time. What feels like reasoning emerges from doing this at a huge scale, with billions of parameters and vast training data.
A: A token is a small piece of text, not always a full word. It can be a word, a word part like “ing”, a single character, or a special marker. For GPT-4, one token is roughly three-quarters of a word, so 100 tokens equal about 75 words.
A: The reason is sampling. The model picks from a spread of likely tokens rather than one fixed answer. Lower the temperature in Spring AI’s ChatOptions, and the replies become far more stable and repeatable.
A: An embedding turns a token into a vector of numbers that captures meaning. Similar words sit close together, so the model can even do math with meaning: king minus man plus woman lands near queen. This also powers search and RAG in Spring AI.
So there you have it. The whole mystery of LLMs comes down to one humble loop. The model guesses the next token, adds it, and then guesses again.
Let us quickly recap the journey:
Once this clicks, Spring AI stops feeling like magic. You can see why prompts, tokens, and chat options behave the way they do. As a result, you can build smarter, cheaper, and more reliable AI apps.
In the next articles, we will keep building on this base. For now, you understand the engine under the hood. And that changes everything.