Service Decomposition and Bounded Contexts: How to Split a System Without Over-Splitting It
-
Last Updated: October 19, 2026
-
By: javahandson
-
Series

Learn service decomposition using DDD bounded contexts, define clear microservice boundaries, and avoid over-splitting into nano-services.
Most teams do not plan to build a mess. They plan to build microservices, and the mess shows up on its own. One day you have a clean monolith that everybody understands. A year later you have forty services, nobody is sure who owns what, and a simple change to the checkout flow touches six repositories. This is the exact spot where service decomposition goes from an exciting idea to a daily headache.
This article is about drawing service boundaries well. We will look at how to break a large system into smaller services. We will see how Domain-Driven Design and its idea of bounded contexts guide those cuts. And — just as important — we will look at how to avoid slicing things so thin that you create new problems. The topic sits right at the heart of system design, and it is one of the most common places where good engineers make expensive mistakes.
I am writing this for developers who already know how to build an application but are now being asked to think about structure. Maybe your monolith is groaning. Maybe your architect said the word “microservices” in a meeting and everyone nodded. Either way, the goal here is to give you a practical way to reason about boundaries, so you split where it helps and stay joined where it does not. We will keep the language plain and use small, concrete examples throughout.
By the end, you should be able to look at a system and say, with reasons, where the natural seams are. You will also have a short list of warning signs that tell you a split has gone too far. That second skill is rarer than the first, and it is the one that saves teams from quiet, slow-building pain.
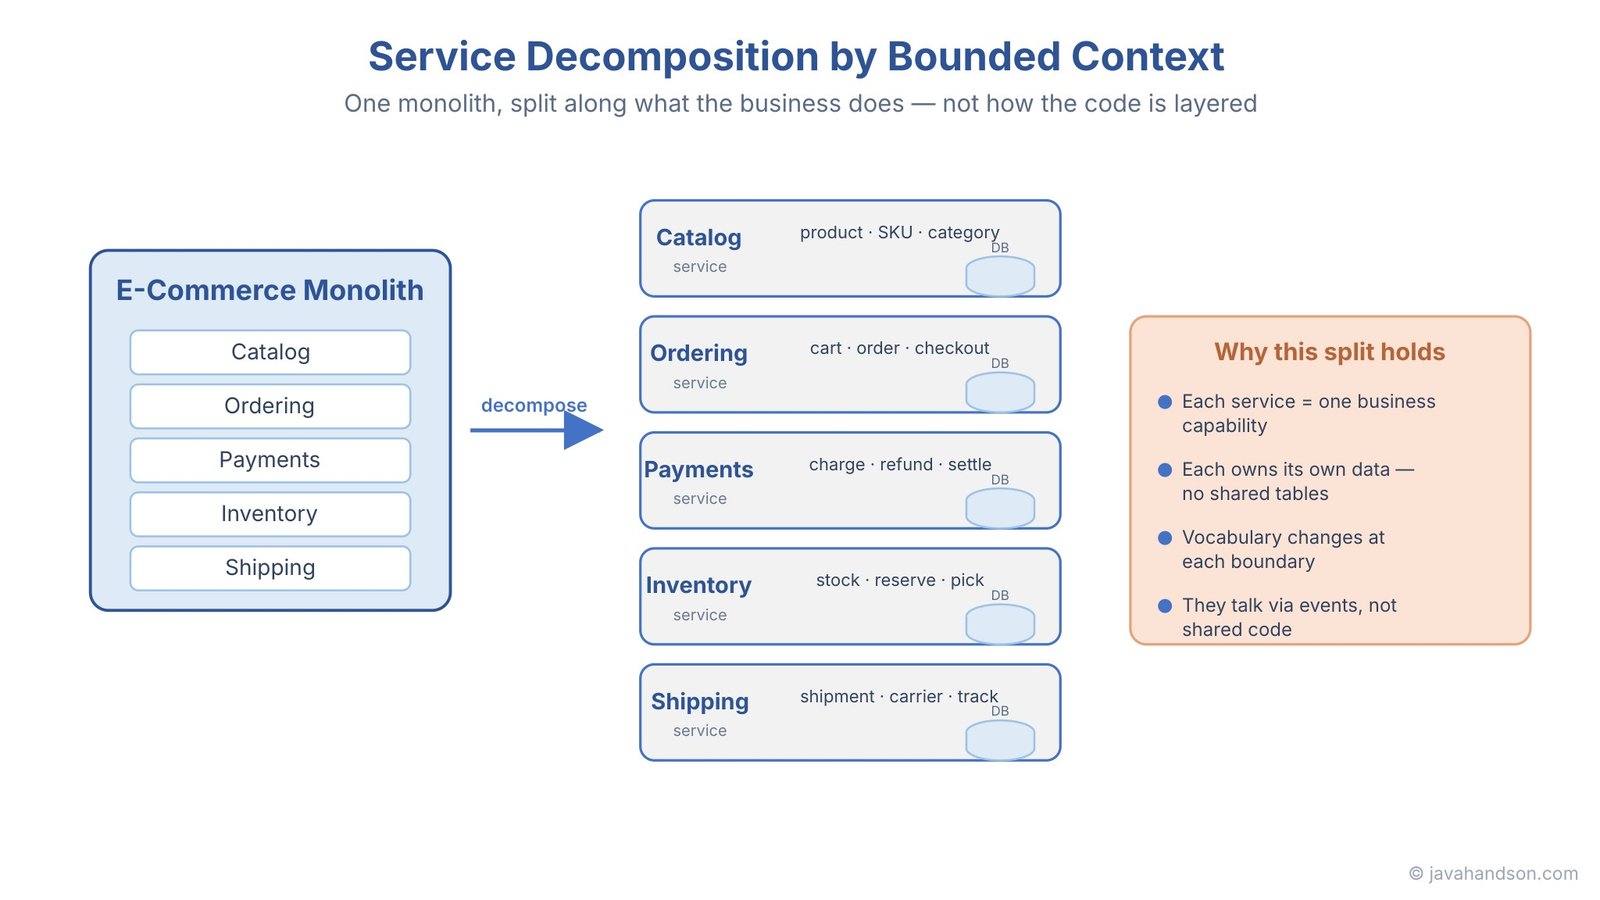
Service decomposition is the act of taking one large system and dividing it into smaller, independent services that each own a clear slice of the work. Each service runs on its own, holds its own data, and talks to the others through well-defined interfaces. That is the textbook version. The real version is messier, because the hard part is not the splitting — it is deciding where to split.
Think about a kitchen in a busy restaurant. You could have one cook do everything from starters to desserts. That works when orders are few. As the place fills up, you split the work: one station for grilling, one for salads, one for plating. Notice what makes this split sensible. Each station owns a clear job, the stations rarely step on each other, and a ticket flows through them in a predictable way. A bad split would be giving one person the left half of every plate and another person the right half. Technically it is a division of labour, but it creates chaos because the boundary runs through the middle of a single task.
Software decomposition works the same way. A good boundary follows a natural line in the business. A bad boundary cuts across one. When you get it right, teams move fast because changes stay inside one service. When you get it wrong, every feature becomes a negotiation across three teams, and your “independent” services turn out to be joined at the hip.
It helps to remember why we bother, because the reasons also tell us where to stop. We split a system for a few down-to-earth benefits.
Every one of those benefits assumes the boundary matches real independence. If two services always change together, you get none of these gains and all of the costs. So the question behind every split is simple: are these two things actually independent, or do they just look separate on a diagram?
When developers first break up a monolith, they often reach for the layers they already know. We have controllers, services, and repositories, so why not make a controller service, a business-logic service, and a data service? It feels tidy. It is also one of the most common decomposition mistakes, and it is worth understanding why before we reach for a better approach.
The problem is that technical layers are horizontal, but features are vertical. A real feature — say, “place an order” — needs a controller, some logic, and some data all at once. If those three live in three separate services, then one small feature now spans three deployments, three teams, and three network calls. You have not removed the coupling. You have spread it across the network and added latency on top.
Here is the rule of thumb I keep coming back to: split by what the system does, not by how it is built. Business capabilities make good services because a change to a capability usually stays inside that capability. Technical layers make poor services because almost every change cuts across all of them.
| Interview Insight If an interviewer asks you to decompose a system and your first move is to name a “database service” or an “API layer service,” expect a follow-up question that exposes the coupling. A stronger opening is to list the business capabilities first — ordering, payments, inventory, shipping — and treat each as a candidate service. This shows you split along the grain of the business, which is exactly what senior reviewers look for. |
Domain-Driven Design, usually shortened to DDD, gives us the single most useful tool for this job: the bounded context. The name sounds heavy, but the idea is light once you see it. A bounded context is a part of the system where a particular model, and the words that describe it, hold one clear meaning. Cross the boundary, and the same word can mean something different.
The classic example is the word “customer.” In the sales part of a business, a customer is a lead with a pipeline stage and a sales owner. In the billing part, a customer is an account with an address and a payment method. In the support part, a customer is a person with a ticket history. Same word, three different meanings, three different sets of data. Each of those is a bounded context.
This matters for decomposition because bounded contexts are natural service boundaries. Inside a context, the model is consistent and the team shares a vocabulary. Between contexts, you translate. When you draw your services along context lines, your boundaries line up with how the business actually thinks, and that alignment is what keeps services independent over time.
DDD puts a lot of weight on something it calls the ubiquitous language. In plain terms, it means the code and the business should use the same words. If the warehouse team says “consignment” and “pick list,” then your inventory service should have classes and endpoints that say consignment and pick list too. Not “item batch” or “fulfilment unit” or whatever a developer invented on a Tuesday.
Why does this help with boundaries? Because the places where the language changes are usually the places where the context changes. When you notice the team suddenly using a new vocabulary — new nouns, new verbs, a different meaning for an old word — you have very likely crossed into a new bounded context. That shift in words is a free hint about where a service boundary wants to be.
Finding contexts is less about theory and more about listening. A few practical signals help you spot them without a whiteboard full of UML.
None of these needs a heavy process. You can get surprisingly far just by sitting with the business for a day and writing down every noun they use and who owns it. The clusters almost draw themselves.
Let us make this concrete with a system most people can picture: an online store. It started as one application that does everything — browsing products, placing orders, taking payments, managing stock, and shipping parcels. It works, but releases are slow and the team keeps stepping on each other. We want to decompose it. The numbers and details below are made up for the example, not from any real company.
First, we ignore the code structure completely and ask what the business actually does. Talking to the team, a handful of clear capabilities show up again and again. Each one has its own vocabulary, its own data, and its own group of people who care about it. These are our candidate bounded contexts.
| Capability / Context | What it owns | Core vocabulary |
|---|---|---|
| Catalog | Products, descriptions, prices, categories | product, SKU, category, listing |
| Ordering | Carts, orders, order status | cart, order, line item, checkout |
| Payments | Charges, refunds, payment methods | charge, refund, authorization, settlement |
| Inventory | Stock levels, reservations | stock, reservation, warehouse, pick |
| Shipping | Shipments, tracking, carriers | shipment, tracking number, carrier, delivery |
Notice how little these overlap in language. The catalog team talks about SKUs and categories. The shipping team talks about carriers and tracking numbers. They barely use the same words, which is a strong sign they belong in separate contexts. That is five candidate services, each owning a clear slice.
Follow a single order through the system and you can see the contexts translate. In Ordering, an order is a cart that a customer confirmed, with line items and a total. Payments hears about it and does not care about line items at all — it cares about an amount to charge and who to charge. Inventory, meanwhile, cares about which items to reserve and reduce. Shipping cares only about an address and a box.
Same order, four different views. Each context keeps only the part of the order it needs, in its own shape. Nobody tries to build one giant shared “Order” object that every service imports, because that shared object would chain all five services together. The translation between contexts is the price we pay to keep them independent, and it is a price worth paying.
A boundary is only real if the data respects it. The firmest rule in healthy decomposition is this: a service owns its data, and no other service reaches into that data directly. Payments does not run queries against the Ordering database. If Payments needs order information, it asks Ordering through an interface, or it keeps its own small copy of just what it needs.
This feels wasteful at first — why copy data? — but it is what buys you independence. The moment two services share a database table, they are no longer independent. A schema change for one breaks the other, and you are back to coordinating releases, which was the whole thing you were trying to escape. Separate data is the backbone of a separate service.
Payments keeps only the fields it needs, instead of importing a giant shared Order.
// GOOD: Payments defines its own small view of an order.
// It stores just what it needs to charge a card — nothing more.
public class PaymentOrder {
    private final String orderId;     // reference back to Ordering
    private final long   amountCents; // what to charge
    private final String currency;

    // No line items, no shipping address, no product details.
    // Those belong to other contexts, not to Payments.
    public PaymentOrder(String orderId, long amountCents, String currency) {
        this.orderId    = orderId;
        this.amountCents = amountCents;
        this.currency   = currency;
    }
}
The comment in that example is the real lesson. Payments resists the urge to know everything about an order. It keeps a tiny, purpose-built view. That restraint is what lets Ordering change its own internals freely, as long as the amount and currency it reports stay stable.
Splitting is only half the work. The split services still need to cooperate, and the way they talk can quietly glue them back together if you are not careful. There are two broad styles, and choosing between them is a real design decision, not a detail.
The obvious option is a direct call. Ordering calls Payments over HTTP and waits for a yes or no. This is easy to reason about and easy to debug, which is why most teams start here. The downside is coupling in time: if Payments is slow or down, Ordering is stuck waiting. String enough of these calls together and one slow service can freeze a whole chain of them.
The other option is events. When an order is confirmed, Ordering publishes an “OrderPlaced” event and moves on. Payments, Inventory, and Shipping each listen and react in their own time. Now Ordering does not wait for anyone, and a slow Payments service no longer blocks a sale. The trade is complexity: you have to handle events arriving late, out of order, or more than once.
The deeper point is that events keep contexts independent in a way that direct calls do not. With an event, Ordering announces a fact — this order happened — and does not care who listens. It does not know about Payments at all. That ignorance is healthy. The fewer services a service knows about by name, the looser the whole system stays.
| Interview Insight A classic interview trap is to decompose a system into neat services and then wire them together with a long chain of synchronous calls. The interviewer will ask what happens when the third service in the chain slows down, and the honest answer is that everything upstream slows with it. Mention event-driven communication for the steps that can happen in the background, and explain that it stops one slow service from dragging down the rest. That single trade-off — simplicity of sync versus resilience of async — is something senior candidates are expected to discuss clearly. |
| Aspect | Synchronous call | Asynchronous event |
|---|---|---|
| Ease of understanding | High — a direct request and reply | Lower — flow is spread out |
| Coupling in time | Tight — caller waits | Loose — fire and forget |
| Failure handling | One slow service blocks the chain | Services recover on their own |
| Best for | Reads and instant answers | Background work and side effects |
Now for the part most articles skip. Splitting feels productive, so teams keep doing it, and they cross the line from helpful to harmful without noticing. The result has a nickname: nano-services. These are services so small that the cost of running them dwarfs the value of having them separate. Avoiding this trap is a core skill, and it is mostly about knowing when to stop.
The usual story goes like this. A team splits “user” into a user service. Then someone splits authentication out of that. Next, password reset becomes its own service, and email verification follows soon after. Each split looked reasonable alone. Together they created five services that always change as a group, always deploy together, and spend most of their time making network calls to each other. The team rebuilt a monolith, except now it is slow and spread across the network.
You rarely get a loud alarm when a split goes wrong. Instead you get a slow drip of friction. Here are the signs I watch for, and any two of them together should make you pause.
Each of these says the same thing in a different voice: the boundary you drew does not match a real seam in the problem. The pieces want to be together. When you see this, the fix is not more services. The fix is fewer.
It helps to remember that every service you create is not free. People talk a lot about the benefits of splitting and forget the running costs, which are real and recurring.
A split is worth it only when the benefit — independence, focused scaling, clear ownership — clearly beats this bill. For a seam that runs through the middle of one tight job, the bill wins, and you should leave the pieces joined. This is the quiet judgement that separates a thoughtful architecture from a fashionable one.
It is worth saying plainly, because the industry often forgets it: a well-organised monolith is a perfectly good design. For a small team, or a product still finding its shape, one codebase is usually faster to build and far easier to change. You keep clean module boundaries inside it, and you split out a service only when a real need appears — a part that must scale alone, or a piece a separate team must own.
This idea even has a popular name: the modular monolith. You draw your bounded contexts as modules within a single application, with clear internal boundaries, but you deploy them together. Later, if a module genuinely needs to be independent, its clean edges make it easy to lift out into its own service. You get the clarity of good boundaries without paying the network bill until you must. Starting here and splitting later is usually smarter than splitting everything up front.
After all the theory, it helps to have a short set of questions you can actually run through when staring at a system. I use something like this before committing to any split. If a candidate service fails several of these, I leave it joined to its neighbour.
Run a candidate through these six questions and the answer is usually obvious. Clear yeses across the board mean you have found a genuine boundary. A scatter of noes means you are about to create a nano-service, and you should think again. The checklist will not design the system for you, but it keeps you honest.
| Interview Insight When you are asked to decompose a system in an interview, narrate this checklist out loud as you draw. Say why each service maps to a capability, why it owns its data, and why you are choosing not to split a particular piece further. Interviewers are often more impressed by a split you refuse to make — with a clear reason — than by one more box on the diagram. Restraint, explained well, signals real experience. |
A few traps catch almost everyone the first time around. Knowing them in advance saves a lot of rework, so here are the ones I see most, each with the reasoning behind it.
There is a comforting belief that boundaries can be moved easily once the system is running. In practice, moving a boundary after launch is one of the hardest changes you can make. Data has to migrate, two teams have to coordinate, and live traffic cannot stop while you do it. Getting the big boundaries roughly right at the start matters far more than people admit.
This is exactly why the modular-monolith path is so appealing. Inside one codebase, moving a boundary is a refactor, not a migration. You can reshape modules cheaply while you still learn the domain, and only harden them into services once they have proven stable. Delaying the expensive, hard-to-reverse decision is good engineering, not procrastination.
System design interviews love this topic because it reveals how you think under a little pressure. The strongest candidates do not rush to draw boxes. They start by naming business capabilities, group them into contexts, and only then propose services. That order — domain first, services second — is the signal reviewers are listening for.
Expect to be pushed on granularity. An interviewer may ask, “why not split this further?” and the answer they want is not a longer list of services. It is a clear reason to stop: these pieces change together, they share a tight transaction, or the running cost would outweigh any gain. Being able to defend a boundary you chose not to cross is often what sets a senior answer apart from a junior one.
Finally, be ready to talk about communication. Once you have your services, say how they will talk and why. Point out which calls can be asynchronous events to keep the system resilient, and which must be synchronous because the user needs an instant answer. Tying the boundaries to the communication style shows you understand that decomposition and resilience are two halves of the same decision.
Turning all of this into habits is what makes it stick. A handful of simple rules will carry you through most real decomposition work, whether you are breaking up a monolith or designing something new.
Here is a compact glossary of the core terms from this article, so you can revisit them quickly.
| Term | Meaning in one line |
|---|---|
| Service decomposition | Splitting one system into smaller, independent services |
| Bounded context | A part of the system where a model and its words have one clear meaning |
| Ubiquitous language | Using the same words in code as the business uses |
| Business capability | A recognisable job the business does, like ordering or shipping |
| Data ownership | Each service owns its data; others ask instead of reaching in |
| Nano-service | A service split so small its cost outweighs its benefit |
| Modular monolith | One deployable app with clean internal module boundaries |
| Synchronous call | A direct request where the caller waits for a reply |
| Asynchronous event | A published fact that other services react to in their own time |
A: Service decomposition is the practice of breaking one large system into smaller, independent services that each own a clear slice of the work, their own data, and well-defined interfaces. The goal is independent deployment, focused scaling, and clear ownership — but only where the pieces are genuinely independent.
A: A bounded context is a part of the system where a particular model and its vocabulary hold one clear meaning. The same word, like “customer,” can mean different things in sales, billing, and support. Each of those is a separate bounded context, and these context lines make natural service boundaries.
A: Technical layers are horizontal, but features are vertical. A single feature needs a controller, logic, and data together. Putting those in separate services spreads one feature across three deployments and network calls, which adds latency without removing the coupling. Split by business capability instead.
A: Nano-services are services split so small that the cost of running them outweighs the value of keeping them separate. They tend to deploy in lockstep, chatter constantly over the network, and change together for every feature — effectively a monolith that is now slow and spread across the network.
A: Watch for warning signs: services that always deploy together, a single user action triggering long chains of calls, features that force edits across several services at once, and a service whose code is mostly glue calling other services. Any two of these together mean the boundary does not match a real seam.
A: No. A well-organised monolith is a perfectly good design, especially for small teams or products still finding their shape. A modular monolith lets you draw clean bounded-context modules inside one deployable app and extract a service only when a real need — independent scaling or separate team ownership — actually appears.
Service decomposition is less about cutting a system into as many pieces as possible and more about finding the seams that are already there. Bounded contexts from Domain-Driven Design give you a reliable way to find those seams: look for where the model and the language change, and draw your boundaries there. Split along business capabilities, give each service its own data, and let the words of the business guide your hand.
The harder discipline is restraint. Every split carries a permanent bill in latency, operations, and complexity, so a boundary has to earn its keep. When the pieces always change together, deploy together, and chatter constantly, they are telling you to stay joined. A clean monolith with good internal modules often beats a scatter of nano-services that only looks modern on a slide.
Carry two questions into your next design. Where does the business naturally divide? And is this particular split truly worth its cost? Answer those honestly, split where the answer is a confident yes, and hold back everywhere else. Do that, and your services will stay independent, your teams will stay fast, and your architecture will match the problem instead of fighting it.